Claude Sonnet 5.5 costs $2 per million input tokens and $10 per million output tokens, with cache reads at $0.10 per million, half the $0.20 that Sonnet 5 charges, on Anthropic’s pricing page as of 20 October 2026. The cache read is the only line that differs from Sonnet 5: Anthropic cut it on 7 October, nine days after the model shipped. On the cache-heavy agent task I price below, that single line takes 17.5 percent off the bill, while a job that is mostly output saves nothing at all.

Sonnet 5.5 costs $2 in, $10 out, and $0.10 to read the cache
Anthropic bills Sonnet 5.5 on five token lines, not two. The Anthropic pricing page lists them in one row, and the model page repeats the same figures. Here is that row as it read on 20 October 2026.
| Price line (per million tokens) | Claude Sonnet 5.5 |
|---|---|
| Base input | $2.00 |
| Cache write, 5 minutes | $2.50 |
| Cache write, 1 hour | $4.00 |
| Cache read (hit) | $0.10 |
| Output | $10.00 |
| Batch input | $1.00 |
| Batch output | $5.00 |
The context window is 1 million tokens at the standard rate all the way through. Anthropic says a 900k-token request is billed at the same per-token price as a 9k-token one, which is not true of every rival in this tier.
Only one line moved since launch
Sonnet 5.5 went on sale on 28 September 2026 at exactly the grid of Claude Sonnet 5 pricing, cache read included at $0.20. Then the Claude Platform release notes of 7 October announced the cut: cache reads went from $0.20 to $0.10 per million tokens, with cache writes and every other price unchanged.
A Sonnet 5.5 cache hit now costs 0.05x the base input price, against 0.1x on Sonnet 5 and on most other Claude models.
Most Claude models still bill a cache hit at a tenth of their input price; Sonnet 5.5 and Opus 5.5 bill it at a twentieth, and Fable 5.1 and Mythos 5.1 at a fortieth, like Fable 5.2 and Mythos 5.2, listed on 9 November 2026.
Batch and US-only routing on top
The Batch API halves input and output, which puts Sonnet 5.5 at $1 in and $5 out. The pricing page states that the cache multipliers stack with the Batch discount, so a batched cache read works out at $0.05 and a batched five-minute write at $1.25.
US-only inference goes the other way. Pinning a request with the inference_geo parameter adds a 1.1x multiplier to every line, which puts input at $2.20, cache reads at $0.11 and output at $11.00. Global routing, the default, stays on the standard grid.
What a cache-heavy task saves
I priced one task the way an agent actually spends tokens: a long fixed prefix, many turns, short answers.
The worked task
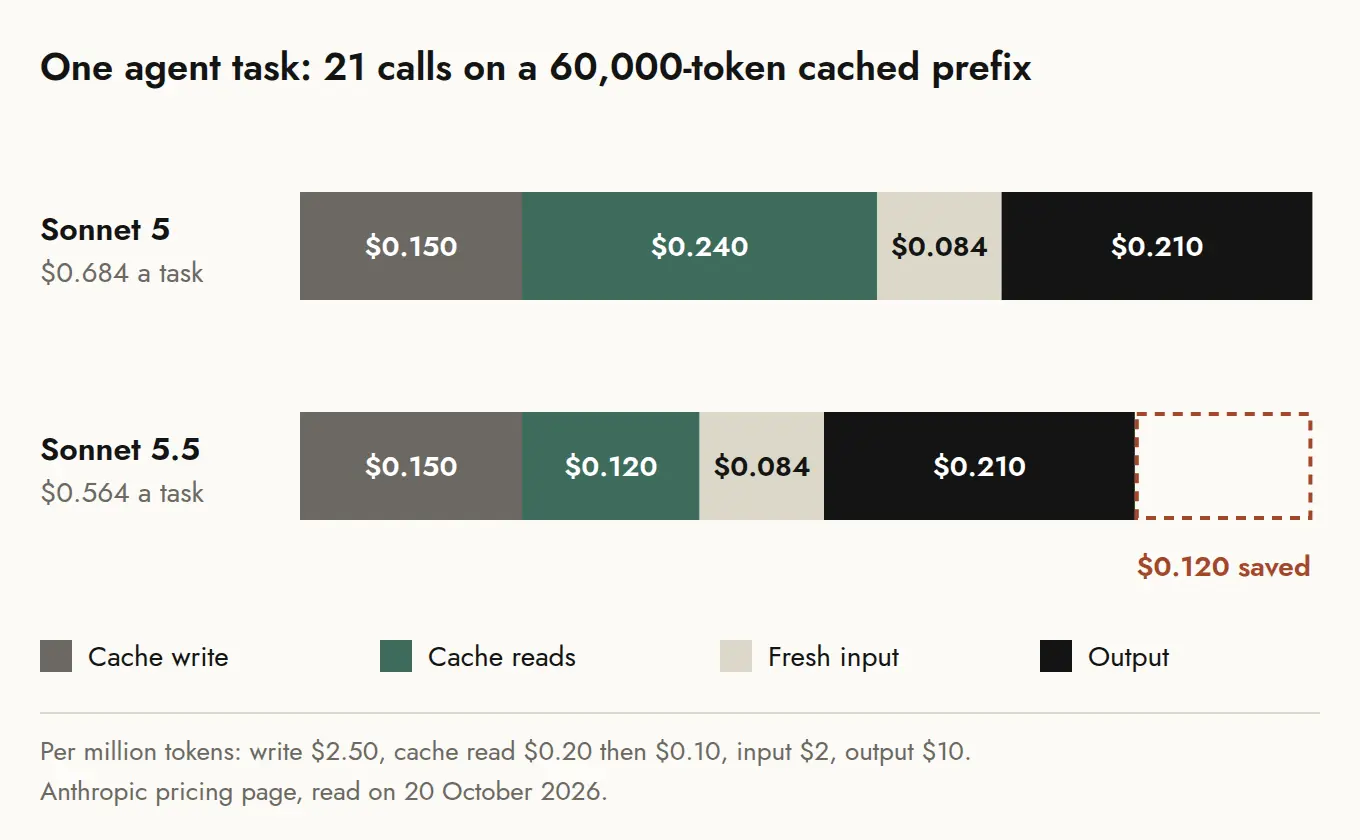
The task runs 21 calls against a 60,000-token prefix (system prompt, tool definitions and a reference document). The first call writes that prefix to the five-minute cache and the next 20 read it back; every call also sends 2,000 fresh input tokens and gets 1,000 output tokens. Sonnet 5.5 uses Sonnet 5’s tokenizer, so the same text produces the same token counts on both models and the comparison holds line for line.
| Line of the bill | Sonnet 5, then Sonnet 5.5 |
|---|---|
| Cache write, 60,000 tokens at $2.50 | $0.150, then $0.150 |
| Cache reads, 1.2 million tokens | $0.240, then $0.120 |
| Fresh input, 42,000 tokens at $2 | $0.084, then $0.084 |
| Output, 21,000 tokens at $10 | $0.210, then $0.210 |
| Total per task | $0.684, then $0.564 |
Run that task 1,000 times and the bill falls from $684 to $564. Nothing else in the row had to change for that $120 to appear.
Where the 17.5 percent comes from
The whole saving sits on one line: 1.2 million cached tokens that now cost $0.10 per million instead of $0.20. In this task the cache reads were 35 percent of the Sonnet 5 bill, and halving them removes 17.5 percent of the total.
Anthropic’s own figure is close. The post that announced the cut, from the official Claude account, put the saving at around 20 percent on long-running work:
One more thing: we’re halving the price of cache reads on Claude Sonnet 5.5, to $0.10 per million tokens. That makes Sonnet 5.5 around 20% cheaper to run on most long-running work.
@claudeai
https://x.com/claudeai/status/2107894060229034197
The share is the variable to check on your own logs. The longer the prefix and the more turns reuse it, the larger the share of the bill the cache reads take, and the saving is always half of that share.
A writing job saves nothing
Take a request with 3,000 uncached input tokens that returns a 4,000-token draft. On both models it costs $0.006 of input and $0.040 of output, $0.046 in all, to the tenth of a cent.
Single-shot generation, translation and summaries of fresh documents fall in that bucket: there, the reasons to move are quality and features, not price.
When the cache pays for itself now
A cache write costs more than plain input, so the first question on any cached workload is how many reads it takes to earn the premium back. The cut changed the answer less than the headline suggests.
Five-minute writes pay back on the first read
The five-minute write costs $2.50 against $2.00 of plain input, a $0.50 premium per million tokens. Each read then saves $1.90 against sending the prefix uncached, so one hit inside the window is already profitable, as it was on Sonnet 5 at $1.80 per read.
One-hour writes still need a second read
The one-hour write costs $4.00, a $2.00 premium over plain input. One read saves $1.90, ten cents short of break-even, so the one-hour cache still needs two hits before it pays.
One-hour cache on Sonnet 5.5: $2.00 premium per million tokens written, $1.90 saved per read. Two reads to break even, same as on Sonnet 5.
The practical rule does not move: use the one-hour cache when requests on the same prefix arrive more than five minutes apart but at least twice an hour. The gap logic is laid out in more detail in my guide to Claude API pricing with the cache.
Prompts from 512 tokens can be cached
The second cache change on Sonnet 5.5 sits in the Sonnet 5.5 migration guide, not on the pricing page. The minimum cacheable prompt is 512 tokens, down from 1,024 on Sonnet 5.
On a chatbot with an 800-token system prompt, which Sonnet 5 could not cache, every turn after the first can read that prefix at $0.10 instead of paying $2.00 for it again.
The output tokens that can eat the saving
Thinking is billed as output
Sonnet 5.5 runs adaptive thinking by default, even on a request with no thinking field, and the migration guide says thinking tokens are billed as output tokens. The cheapest setting, between_tools, turns off up-front thinking; the old disabled value from Sonnet 5 now returns a 400 error.
Artificial Analysis measured the other side of the trade on launch day. Its post on Sonnet 5.5 pairs a near-Opus score with a token count it calls the highest it has seen per task:
Anthropic has launched Claude Sonnet 5.5: it scores 56 on the Artificial Analysis Intelligence Index, just 2 points behind Opus 5.5 (max), but at the highest Output Tokens per Task we’ve seen
With max effort, Sonnet 5.5 gains 18 points over Sonnet 5 and to #2 on the Intelligence@ArtificialAnlys
https://x.com/ArtificialAnlys/status/2104640155843989864
Back on the worked task, the $120 saved per 1,000 runs equals 12,000 output tokens per run. If Sonnet 5.5 writes about 57 percent more output than Sonnet 5 did on the same job, the cache saving is gone.
Effort levels were recalibrated
Sonnet 5.5 has five effort levels, from low to max, with high as the default on the Claude API. Anthropic says the levels are recalibrated, so the same level does not produce the same amount of thinking as on Sonnet 5.
Before you trust any saving, re-baseline cost, as the migration guide recommends:
- replay a sample of real tasks on both models at the effort level you use today;
- read
output_tokensand the cache fields in each response’susageblock; - repeat at one level lower, since
mediumis Anthropic’s suggested start for well-specified agent work.
Sonnet 5.5 next to Sonnet 5, Opus 5.5 and GPT-6.1 Sol
The cut puts Sonnet 5.5 on the same short-context row as OpenAI’s newest Sol model, at half the cache price of Sonnet 5 and Opus 5.5. These are the input, cache read and output prices per million tokens from each provider’s pricing page on 20 October 2026.
- Claude Sonnet 5.5: $2.00, $0.10 and $10.00, flat across its 1 million-token window.
- Claude Sonnet 5: $2.00, $0.20 and $10.00.
- Claude Opus 5.5: $4.00, $0.20 and $20.00.
- GPT-6.1 Sol: $2.00, $0.10 and $10.00 up to 272K input tokens, then 2x input and cache and 1.5x output on the whole request.
On short prompts the two match to the cent, cache writes included at $2.50. Past 272K tokens, GPT-6.1 Sol pricing rises to $4.00, $0.20 and $15.00 while Sonnet 5.5 stays put, so long-context work is cheaper on the Claude side.
Should you move a Sonnet 5 workload now?
On price alone, yes for anything that reuses a long prefix, provided the output count holds. Sonnet 5.5 is never dearer than Sonnet 5 per token, and on a cached agent loop it is cheaper by half the share of the bill that cache reads used to take.
The move is not free in engineering time. Anthropic lists five breaking changes from Sonnet 5, among them forced tool use, which now returns a 400 error, and thinking blocks tied to the model and the conversation.
My order of priority is short:
- move cached agent and RAG pipelines first, after the output check above;
- leave output-heavy generation on Sonnet 5 until you need a Sonnet 5.5 feature, since the bill will not move;
- migrate anything still on Sonnet 4.5 regardless, because Anthropic retires it from the Claude API on 30 November 2026.