Groq no longer sells llama-3.1-8b-instant or llama-3.3-70b-versatile to free or pay-as-you-go accounts: as of 20 October 2026, both rows on its models page read Contact Sales. The self-serve replacement for the old $0.05 tier is openai/gpt-oss-20b at $0.075 / $0.30 per million input / output tokens, with half price on cached input. It costs more than Llama 3.1 8B did, mostly on output, while gpt-oss-120b actually undercuts the old Llama 3.3 70B price.

What changed on Groq’s Llama rows
Groq’s Supported Models page still lists both Llama models among its Production Models, now with an Enterprise tag next to the name. The price column and the Developer-plan rate-limit column both say Contact Sales, where a per-token price used to sit. Speed (560 and 280 tokens per second) and the 131,072-token context window did not move.
The two IDs that left the self-serve grid
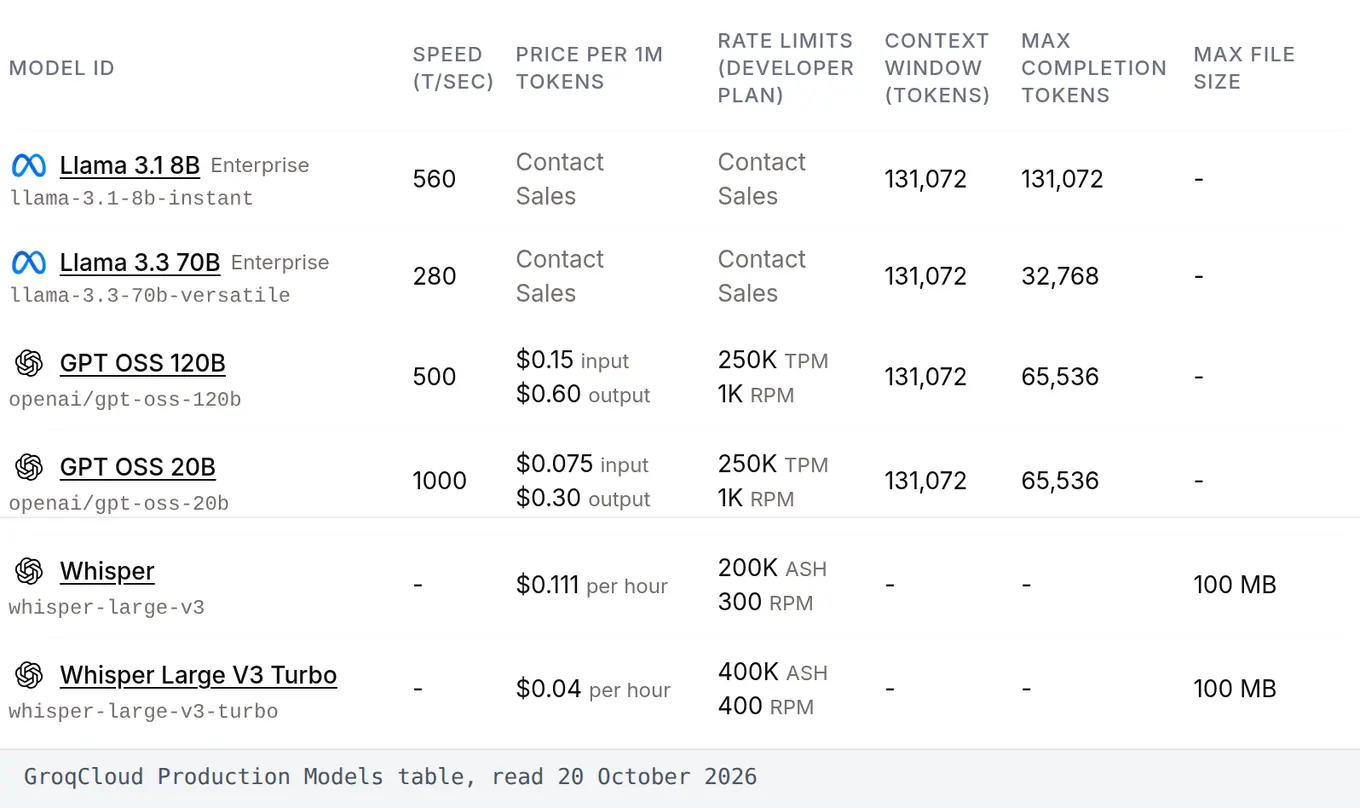
Behind the label is a deprecation for everyone below an enterprise contract. Groq’s deprecation log says it emailed users on June 17, 2026 and set August 16, 2026 as the shutdown date for llama-3.1-8b-instant and llama-3.3-70b-versatile on free and developer-tier usage. The same entry states that enterprise customers with a committed-spend contract are not affected.
Before the switch, the grid was simple. Groq’s models page, as archived on 2 June 2026, priced the two rows like this:
- llama-3.1-8b-instant: $0.05 input and $0.08 output per million tokens, 250K tokens and 1K requests per minute on the Developer plan.
- llama-3.3-70b-versatile: $0.59 input and $0.79 output per million tokens, 300K tokens and 1K requests per minute.
On 2 June 2026, llama-3.1-8b-instant cost $0.05 input and $0.08 output per million tokens on Groq. By October 2026 the same row reads Contact Sales.
What Contact Sales means for a small account
For a developer on the Free or Developer plan, it means the model ID is gone. Neither Llama chat model appears in the rate-limit tables of either plan, so there is no quota to call it against. The models page gives no price for the enterprise route, and I would not build a side project or a small SaaS around a sales call to keep an 8B model alive.
If you picked Llama for the weights themselves (a fine-tune, a license requirement, an eval baseline), the model is not dead, it just left Groq’s self-serve shelf. The hosts that still bill Llama per token are compared on a separate page, with their own spread of prices.
The replacements Groq recommends
Groq names the successors itself in the deprecation entry: openai/gpt-oss-20b for Llama 3.1 8B, and openai/gpt-oss-120b or qwen/qwen3.6-27b for Llama 3.3 70B. Qwen3.6 27B has since been deprecated in turn, with a shutdown date of September 14, 2026, in favor of qwen/qwen3.8-27b. That leaves three self-serve models to set against the old pair:
| Model | Price per 1M tokens (input / output) |
|---|---|
| Llama 3.1 8B (June 2026 grid) | $0.05 / $0.08 |
| gpt-oss-20b | $0.075 / $0.30 |
| Llama 3.3 70B (June 2026 grid) | $0.59 / $0.79 |
| gpt-oss-120b | $0.15 / $0.60 |
| Qwen3.8 27B (preview) | $0.80 / $4.00 |
gpt-oss-20b in place of Llama 3.1 8B
gpt-oss-20b is the fastest text model on the grid, listed at 1,000 tokens per second against 560 for Llama 3.1 8B. It is a reasoning model: Groq’s reasoning docs let you set reasoning_effort to low, medium or high, but not to none, and they describe the reasoning chain as part of the token output. On short classification or extraction prompts, those extra output tokens are where the bill grows.
Groq’s launch post from August 2025 lists what the model brings beyond price, the 128K context and the built-in tools:
OpenAI’s open models are live and already running on Groq. Try gpt-oss-20B and gpt-oss-120B today. Groq delivers 128K context and built-in tools such as code execution and browser search. For the first time, developers and enterprises can deploy open models backed by OpenAI
@GroqLLC
https://x.com/GroqLLC/status/1952779954544164865
One limit to check before you migrate: maximum completion is 65,536 tokens, half of the 131,072 that Llama 3.1 8B allowed.
gpt-oss-120b in place of Llama 3.3 70B
This is the swap that saves money. gpt-oss-120b costs $0.15 input and $0.60 output, so input is almost four times cheaper than the $0.59 of Llama 3.3 70B, and output about a quarter below its $0.79. It also runs at 500 tokens per second against 280, and it sits on the short list of models where Groq’s prompt caching applies.
Qwen3.8 27B, the preview option
Qwen3.8 27B sits in the Preview table at $0.80 input and $4.00 output, with 450 tokens per second, 16,384 maximum completion tokens and a 20 MB file limit for image input. It is the only one of the three that can switch reasoning off entirely (reasoning_effort none), which helps latency-bound chat. Two caveats keep it off my production list: Groq says preview models may be discontinued at short notice, and prompt caching does not cover it.
What the switch does to a real bill
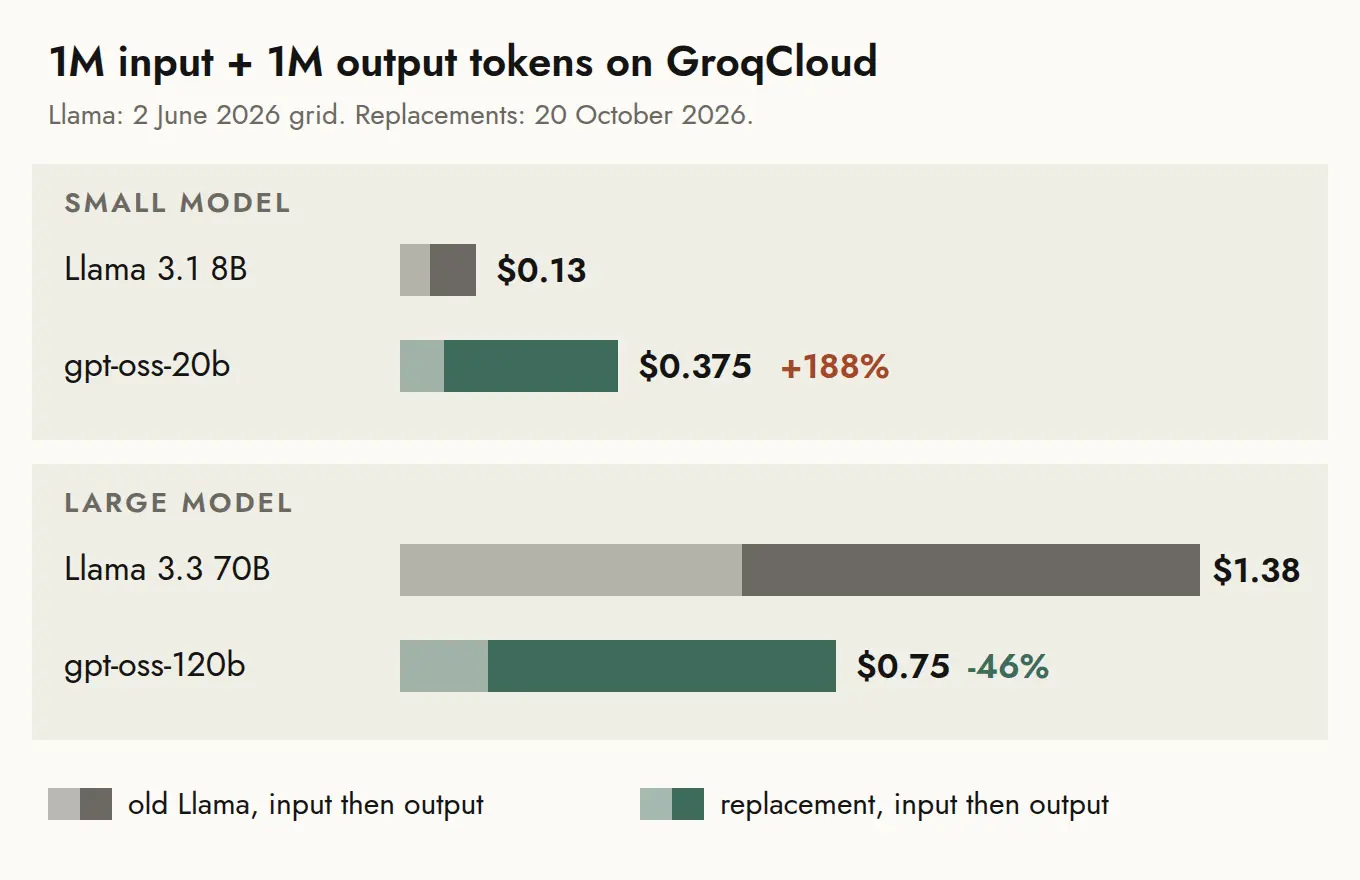
Per-token prices hide the shape of your workload. The chart below puts each pair on the same footing, one million input tokens plus one million output tokens, before any discount.
Where the 8B replacement costs more
At that even mix, Llama 3.1 8B cost $0.13 and gpt-oss-20b costs $0.375, close to three times as much. Input only rose by half, from $0.05 to $0.075, while output rose from $0.08 to $0.30. The more your job writes, the worse the switch looks, and reasoning tokens push in the same direction.
gpt-oss-20b output costs $0.30 per million tokens on Groq, 3.75 times the $0.08 that Llama 3.1 8B charged.
Where the 70B replacement costs less
The same mix cost $1.38 on Llama 3.3 70B and costs $0.75 on gpt-oss-120b, 46% less. If your old stack ran the 70B for quality, the forced migration is a price cut. Qwen3.8 27B comes to $4.80 on that mix, about three and a half times the old 70B, so I would only pay it for the image input.
Cache and Batch, the two discounts that close the gap
Two discounts apply to gpt-oss-20b and can pull it back to Llama 8B territory on input-heavy jobs. Prompt caching bills cached input at half price, works automatically on matching prefixes, and expires after two hours without use. The Batch API takes 50% off every token with a 24-hour to 7-day window, and the two do not stack: batch tokens are billed at the batch rate whatever their cache status.
Take the kind of job the 8B used to win, 10 million input tokens and 1 million output tokens, such as tagging a backlog of support tickets. Before any reasoning tokens, the bill looks like this:
| Setup | Cost of 10M input + 1M output |
|---|---|
| Llama 3.1 8B, June 2026 price | $0.58 |
| gpt-oss-20b, standard | $1.05 |
| gpt-oss-20b, every input token cached | $0.675 |
| gpt-oss-20b, Batch API | $0.525 |
Batch brings gpt-oss-20b just under the old Llama price on this job, as long as you can wait for results. A fully cached input never happens in practice, since only the shared prefix caches, so read that row as a floor rather than a forecast.
Which plan can still run what
The answer is the same list on both self-serve plans. Groq’s rate-limit page gives these text models for the Free and Developer plans, and neither table carries a Llama chat model:
- openai/gpt-oss-20b and openai/gpt-oss-120b: 30 requests per minute and 1K per day on Free, 1K per minute on Developer.
- qwen/qwen3.8-27b: the same Free and Developer request limits as the gpt-oss pair.
- openai/gpt-oss-safeguard-20b: a moderation model at the same price as gpt-oss-20b, not a general chat replacement.
Speech models, Flex processing and the free-plan quotas in detail sit on the full Groq Cloud price grid, which this page does not repeat.
My pick for each old Llama workload
Here is how I would migrate, sorted by what the Llama model was doing in your stack:
- High-volume classification or extraction on Llama 3.1 8B: gpt-oss-20b on the Batch API at low reasoning effort. It lands near the old price if the job tolerates a delay.
- Real-time chat on Llama 3.1 8B: gpt-oss-20b with a stable system prompt at the front, so caching halves the repeated input. Expect the bill to rise anyway, because output is where you pay.
- Quality work on Llama 3.3 70B: gpt-oss-120b, cheaper and faster. Run your evals, then switch.
- Anything that needs image input: Qwen3.8 27B, with a fallback ready, because preview models can disappear.
To set Groq’s replacement against small models from other providers, the ranking of the cheapest LLM APIs right now covers the current floor across the market.
Frequently asked questions
Can I still call llama-3.1-8b-instant on the free plan?
No. Groq shut the model down for free and developer-tier usage on August 16, 2026, and its models page now lists it as Enterprise, Contact Sales. Only customers with a committed-spend contract keep access.
Is gpt-oss-20b cheaper than Llama 3.1 8B was?
No, except on input-heavy work sent through the Batch API. Standard input is $0.075 against $0.05, and output $0.30 against $0.08.
Does prompt caching work on Qwen3.8 27B?
No. Groq’s prompt caching page lists gpt-oss-20b, gpt-oss-120b and gpt-oss-safeguard-20b as the only supported models, with a 50% discount on cached input.
What did Groq recommend instead of Llama 3.3 70B?
gpt-oss-120b or Qwen3.6 27B, and Qwen3.6 27B has since been replaced by Qwen3.8 27B. On price, gpt-oss-120b is the better pick at $0.15 / $0.60.